
API Regression Testing: What Content Regression Testing Catches That Contract Tests Miss
Every team that ships APIs has lived through this incident: nothing failed. The build was green, the contract tests passed, the schema validated. And yet the storefront shows a price of null, the mobile app renders an empty product grid, and support tickets are stacking up.
The API didn't break its contract. It broke its content. API content regression testing is the discipline that catches exactly this: it records what your APIs actually return today, and tells you precisely what changed after the next deploy, data migration, or vendor upgrade.
This guide explains what content regression testing is, where it fits in API regression testing as a whole, how it differs from contract and schema testing, how the snapshot, compare and assess workflow works in practice, and what it takes to run it without drowning in diff noise.
Contract testing validates shape, content regression validates substance
Contract tests (OpenAPI validation, Pact-style consumer contracts, JSON Schema checks) answer one question: does the response have the agreed structure? That's necessary, but it's blind to an entire class of production-breaking changes:
- A price field that changes from
49.99(number) to"49.99"(string). Still valid JSON, still passes loose schemas, still breaks a strongly-typed client. - A product description that silently becomes empty after a CMS migration.
- A localized field that starts returning the fallback language for an entire region.
- An enum value that a downstream system has never seen (
"BACKORDERED"appearing where only"IN_STOCK"/"OUT_OF_STOCK"existed). - A list endpoint that suddenly returns 12 items instead of 200 because a filter default changed.
Here is what that first case looks like on the wire. Both responses below validate against a schema that declares price as optional and loosely typed, which is more common than anyone likes to admit:
// Baseline (last known good)
{
  "sku": "sku-8841",
  "name": "Trail Runner GTX",
  "price": 49.99,
  "currency": "EUR",
  "availability": "IN_STOCK",
  "images": 6
}

// After the pricing service upgrade
{
  "sku": "sku-8841",
  "name": "Trail Runner GTX",
  "price": "49.99",
  "currency": "EUR",
  "availability": "BACKORDERED",
  "images": 0
}
Three changes, zero contract failures, and at least two of them will reach a customer: a typed mobile client that refuses to parse the price, and a product page with no images. A content regression test flags all three, because it doesn't compare the response to a description of what is allowed. It compares the response to what the endpoint returned before.
Contract, schema and content regression testing compared
| Contract / schema tests | Content regression tests | |
|---|---|---|
| Question answered | Is the structure allowed? | Did anything change since the last good state? |
| Source of truth | Hand-written spec or consumer contract | Recorded snapshot of real responses |
| Catches type drift | Only with strict schemas | Yes, always |
| Catches wrong or missing values | No | Yes |
| Maintenance cost | Grows with every field you assert | Grows with noise rules, not with fields |
| Best at | Preventing breaking design changes | Detecting unintended behavior and data changes |
The two are complementary. Keep your contracts: they protect the API design. Add content regression to protect what the API actually serves.
How API content regression testing works: snapshot, compare, assess
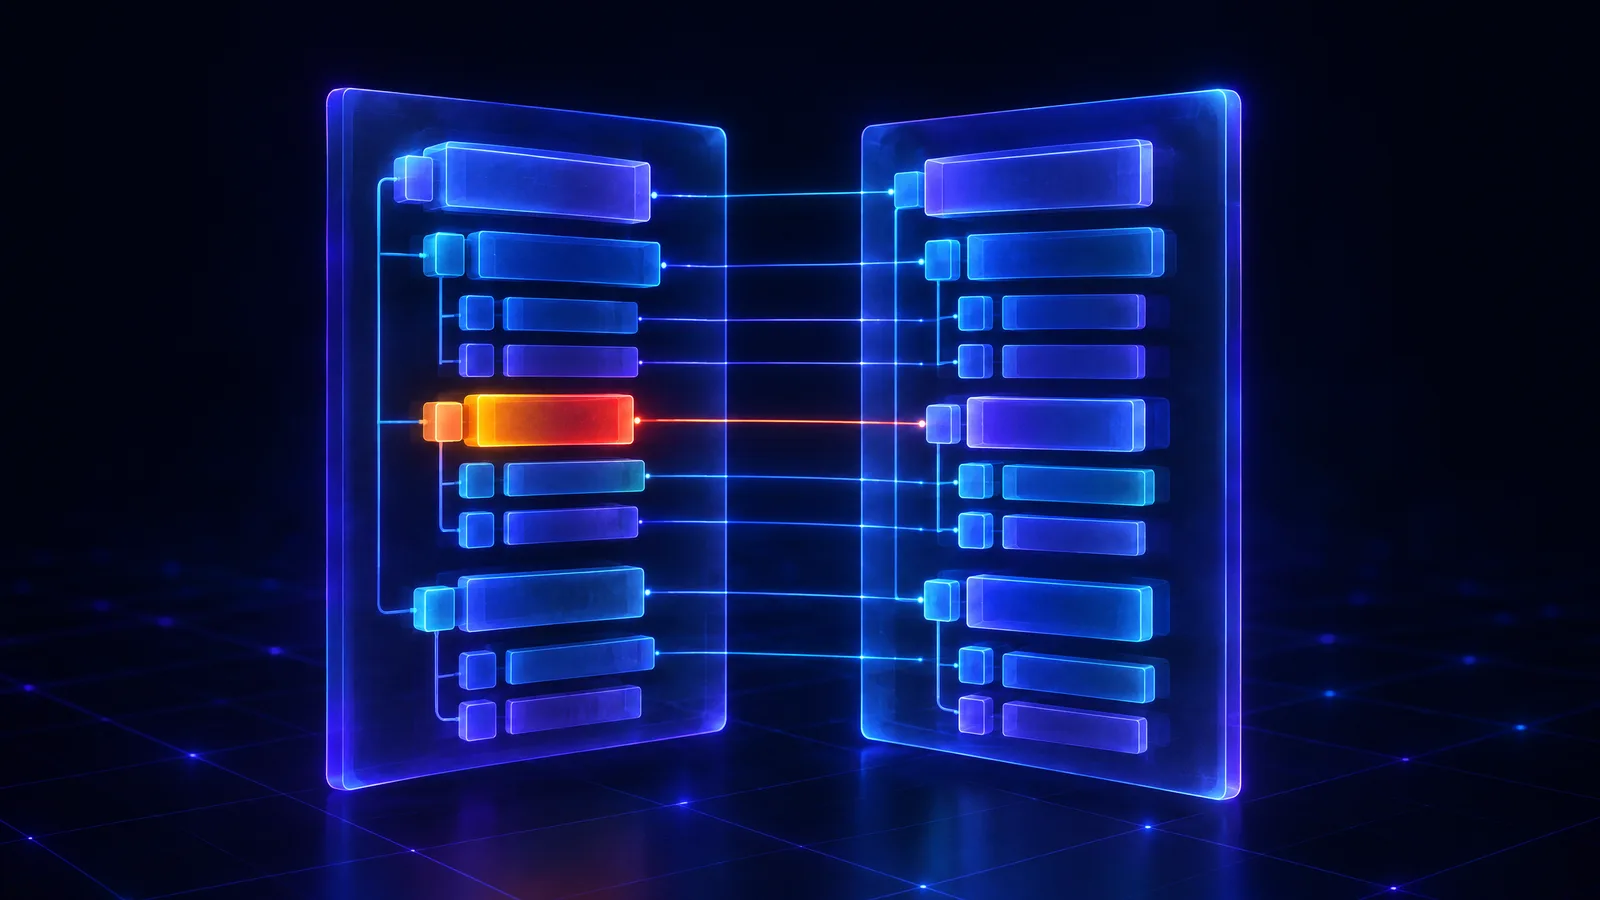
Instead of asserting against a hand-written expectation, content regression testing captures a baseline snapshot of real responses across your endpoints, and then, after a deployment, a data migration or a vendor upgrade, replays the same requests and performs a semantic diff against the baseline.
- Snapshot. Capture responses for hundreds or thousands of endpoint and parameter combinations against a known-good environment. This becomes your source of truth: status codes, headers, bodies, and timing (DNS, TLS handshake, time to first byte).
- Compare. Run the same set against the new build or environment. A structural JSON diff classifies every endpoint: identical, modified, status change, new error, resolved error, or error in both runs.
- Assess. This is where most home-grown diff scripts die: everything changes a little. Timestamps, request IDs, cache headers, A/B flags. A useful regression engine must separate signal from noise, with ignore rules, trainable classifications, and AI-assisted assessment that flags what actually matters and assigns severity (critical, warning, info).
What a semantic diff should understand
A plain text diff of two JSON documents is close to useless: reformatting, key order and a single changed timestamp make every response look different. A semantic API response diff works on the parsed structure and reports changes by JSON path, with a type for each:
$.price           TYPE_CHANGED   number -> string     CRITICAL
$.availability    VALUE_CHANGED  IN_STOCK -> BACKORDERED   WARNING
$.images          VALUE_CHANGED  6 -> 0                WARNING
$.meta.requestId  VALUE_CHANGED  (ignored by rule)     INFO
That output is something a human can triage in seconds, and something a pipeline can make decisions on.
Keeping diff noise under control
Noise is the number one reason API regression testing initiatives get abandoned. If the first comparison flags 400 endpoints because every response carries a fresh timestamp, the team stops reading the report by day three. Plan for noise from the start:
- Ignore rules by path. Fields like
$.meta.requestId,$..updatedAtor theDateandETagheaders change on every call by design. Exclude them once, centrally. - Train on approvals. When a reviewer approves an expected change (a rotating A/B flag, a new cache header), that decision should become a rule that applies to future comparisons, so the same change is never flagged twice.
- Order-insensitive comparison for unordered lists. Recommendations and facet lists often reorder between calls without anything being wrong.
- Severity, not just "changed". A type change or a new 500 is critical. A different value in a significant field is a warning. Volatile metadata is info. A changed cache header should never page anyone; a changed price should.
- Stable test data. If the catalog under test changes every night, your baseline is stale by morning. Pin the data you test against; our guide to test data management for e-commerce QA covers how.
In APIpact, the assessment step combines ignore rules with AI classification: each detected change gets a severity and a plain-language explanation of what changed and who it is likely to affect, so a product manager can read the report as easily as a QA engineer.
Why this matters most in headless commerce
Headless and composable architectures multiply the surface area: a storefront may compose responses from a commerce engine, a CMS, a search service, a pricing service, and a promotions engine. Each vendor ships on its own cadence. Your team is the integration point, and the first to be blamed when content is wrong.
Content regression testing gives you a tripwire across that entire surface: run a comparison after every vendor release, every config change, every catalog import, and know in minutes whether anything a customer sees has changed. Typical moments to run one:
- After every deploy to staging, as an automated gate (see catching breaking API changes in CI/CD for the pipeline pattern).
- Before and after a SaaS vendor upgrade you don't control.
- Around catalog imports, CMS migrations and pricing rule changes.
- When promoting a release between environments, comparing staging against production.
Many of those environments are not reachable from the public internet, which is why a regression platform also needs a way in that the security team will accept. Remote executors for API testing behind the firewall solve that with outbound-only connections.
REST and GraphQL
For REST, the URL space is the test space: enumerate your endpoints and parameter combinations, snapshot them, compare. GraphQL has one endpoint and responses shaped by the query, so the regression surface becomes a curated set of named queries and variables, usually the operations your clients actually send. The workflow is otherwise identical. We cover the details, including partial errors and federation, in our GraphQL regression testing guide.
What a mature content regression setup looks like
Use this as a checklist when evaluating your current approach or a tool:
- Baselines per environment (dev, staging, production) with controlled promotion of new baselines.
- Coverage of the endpoints that matter, ideally checked against your OpenAPI spec so untested endpoints are visible.
- Diff noise reduction that you can train: approve expected changes once, never see them flagged again.
- Severity classification so a changed cache header doesn't page anyone, but a changed price does.
- CI/CD triggers via API, so comparisons run automatically on every deploy.
- Access to private environments without opening inbound firewall rules.
- One-click issue creation (for example in JIRA) from a failed comparison, with the diff attached.
Getting started with API content regression testing
You don't need full coverage on day one. A practical first week looks like this:
- Pick the 50 to 200 endpoint calls that back your most important customer journeys: product detail, listing, search, cart, checkout, account.
- Take a baseline snapshot against a known-good environment.
- Run a comparison against the same environment immediately. Everything it flags is pure noise: turn it into ignore rules.
- Run comparisons after the next few deploys and review the results together. Approve expected changes so they are learned.
- Once the report is quiet on a normal deploy, wire it into CI and fail the build on critical changes.
That's precisely the workflow APIpact was built around, for REST and GraphQL alike. If your team is still eyeballing responses in Postman after each release, book a walkthrough and we'll show you what a baseline of your API surface would look like.
Frequently asked questions
What is the difference between API regression testing and contract testing?
Contract testing checks that a response matches an agreed structure (a schema or consumer contract). API regression testing checks that behavior and data have not changed unexpectedly compared with a previous known-good state. Content regression testing is the form of regression testing that compares full real responses, so it catches wrong values, missing data and type drift that a contract allows.
Does content regression testing replace unit or integration tests?
No. Unit and integration tests verify the logic you intended to write. Content regression tests detect changes you did not intend, including ones caused by data, configuration or third-party services that your own tests never exercise. Most teams run both.
How do you handle fields that change on every request?
Exclude them with ignore rules by JSON path or header name (timestamps, request IDs, ETags), and compare unordered lists without regard to order. A good engine also learns from approved changes, so the noise you dismiss once stays dismissed.
Can I run API content regression tests against production?
Yes, for read-only endpoints it is a useful way to detect changes caused by data or vendor updates. Keep write operations (cart, checkout, account changes) in staging or other pre-production environments, where breakage is free and test data can be controlled.
How many of your endpoints changed last month?
If you can't answer that in one query, you don't have a baseline. Bring your API surface to a 30-minute call and we'll estimate what a first snapshot-and-compare run would catch.
Baseline my API surface